Figure 17 — Run profiles
File: fig17_profiles.pdf
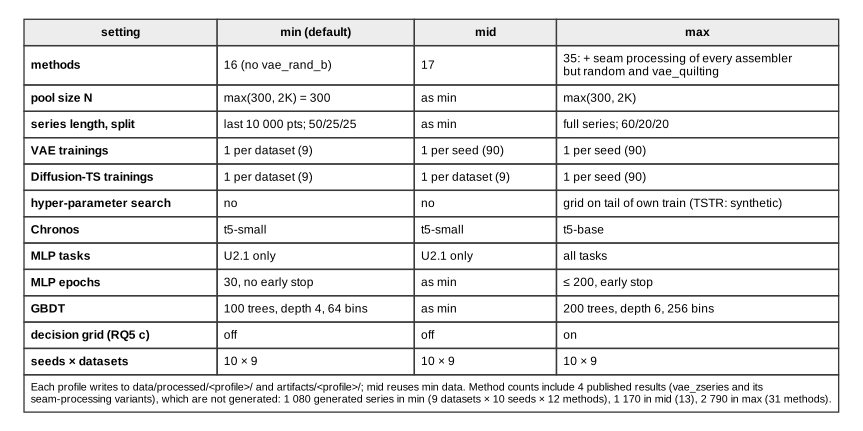
Suggested caption. The three run profiles. min (default, intended for Colab) shares one
trained generator per dataset across seeds. mid retrains the VAE on every seed and adds the noise twin vae_rand_b. max uses
the full series, retrains generators on every seed, and turns on hyperparameter search and the
decision-transfer grid.
Notes for the text
- What a seed varies depends on the profile. In
max, VAE and Diffusion-TS are retrained on every seed, so per-dataset conclusions generalise over the training procedure. Inmin, seeds vary only pool sampling, random paths and model fitting, so conclusions are conditional on the trained generator.midsits in between: the VAE is retrained on every seed, Diffusion-TS once per dataset. mincompares 16 methods,mid17 (+ the noise twinvae_rand_b),max35: inmaxevery seam processing also runs over every assembler except the random path andvae_quilting, not onlyvae_zseries(smooth_paths="all"). Each count includes the 4 published results offrozen_methods(vae_zseriesand its seam-processing variants), which the pipeline does not run. Withoutvae_rand_b(min) the noise is the between-seed spread ofvae_rand. All profiles use the same 9 datasets and 10 seeds.- Profiles write to separate data and artifact folders, so their results never mix. Task
thresholds come from
target_params.json(min,mid) ortarget_params_max.json(max), because themintrain split falls inside val/OOT ofmax. - Source:
marathonts/bench/config.py(Config.profile),BENCHMARK.md.