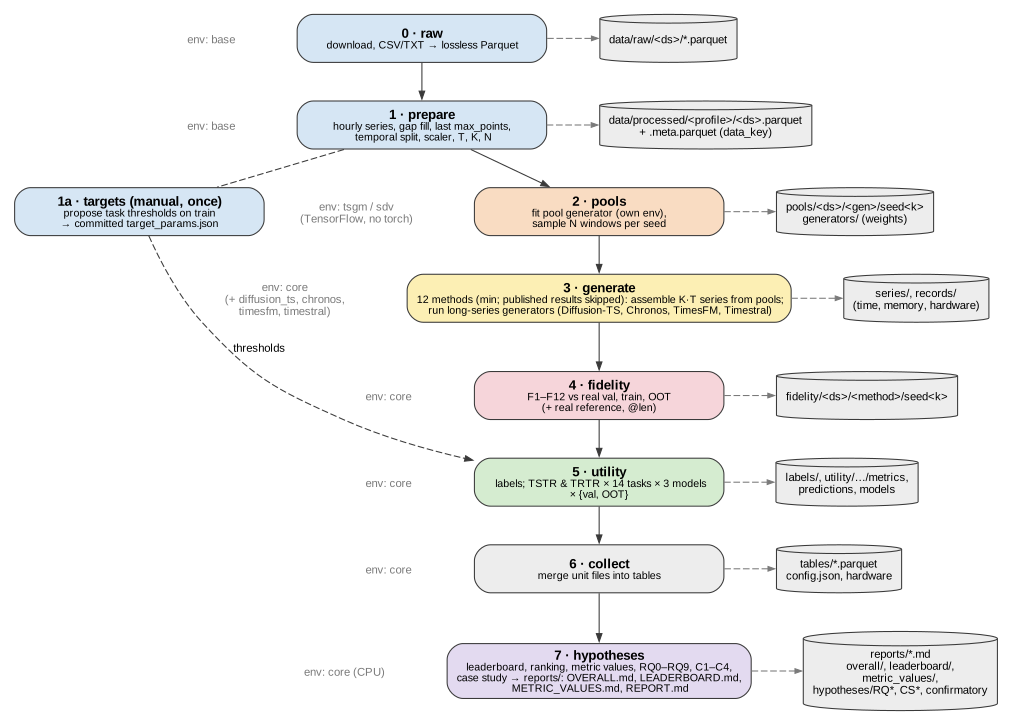
Figure 2 — Stage pipeline
File: fig02_stage_pipeline.pdf
Suggested caption. The benchmark pipeline. Stages run in order. Each one writes its outputs (right) and can run in its own software environment (left). Task thresholds are fixed once on the real training split, committed to the repository, and only read at run time (dashed).
What the figure shows
| Stage | Module | Input → output |
|---|---|---|
| 0 raw | marathonts/bench/datasets.py |
downloads the nine source files, converts CSV/TXT to lossless Parquet → data/raw/<ds>/ |
| 1 prepare | marathonts/bench/data.py |
hourly series, gap handling, temporal split, scaler, T, K, N → data/processed/<profile>/<ds>.parquet + .meta.parquet |
| 1a targets | marathonts/bench/tasks.py |
manual, not part of all: proposes thresholds on train for new datasets → target_params.json (reviewed and committed) |
| 2 pools | marathonts/bench/methods.py, marathonts/bench/generators/ |
fits the pool generator (β-VAE) in its own environment, samples N windows per seed → artifacts/pools, artifacts/generators |
| 3 generate | marathonts/bench/methods.py, marathonts/bench/assemblers.py, marathonts/bench/joiners.py |
builds a series of length K·T for each method it runs (12 in min, 13 in mid, 31 in max; the published results of frozen_methods are skipped): reads pools, runs the long-series generators → artifacts/series, artifacts/records |
| 4 fidelity | marathonts/bench/fidelity.py |
83 metrics F1–F12 against real val, train and OOT → artifacts/fidelity |
| 5 utility | marathonts/bench/utility.py, marathonts/bench/models.py |
labels; TSTR and TRTR for 14 tasks × linear, gbdt (+ MLP on U2.1 in min / mid; on every task in max) × {val, OOT} → artifacts/labels, artifacts/utility |
| 6 collect | marathonts/bench/run.py |
merges unit files into the published tables, the rows of frozen_methods as they are → artifacts/tables |
| 7 hypotheses | marathonts/hypotheses/run.py |
overall leaderboard (OVERALL.md, tables in artifacts/overall), ranking by slice (LEADERBOARD.md, artifacts/leaderboard), metric values by slice (METRIC_VALUES.md, artifacts/metric_values), research questions RQ0–RQ9, confirmatory family C1–C4 and case study (REPORT.md, artifacts/hypotheses); the reports are in artifacts/reports |
Notes for the text
- A unit of work is (dataset, method, seed) for stages 3–5, and (dataset, pool generator, seed)
for stage 2. Each unit writes its own file. A unit is skipped when that file exists and was
produced with the same settings (Fig. 15). A failing unit is logged to
errors.logand the run continues. - Task thresholds are exogenous. They are read from a committed file that records the split they
were computed on (
_split_key). A different split refuses to read them, so thresholds can never come from val or OOT. - Command line:
python -m marathonts.bench.run <stage>,python -m marathonts.bench.run all,python -m marathonts.hypotheses.run.